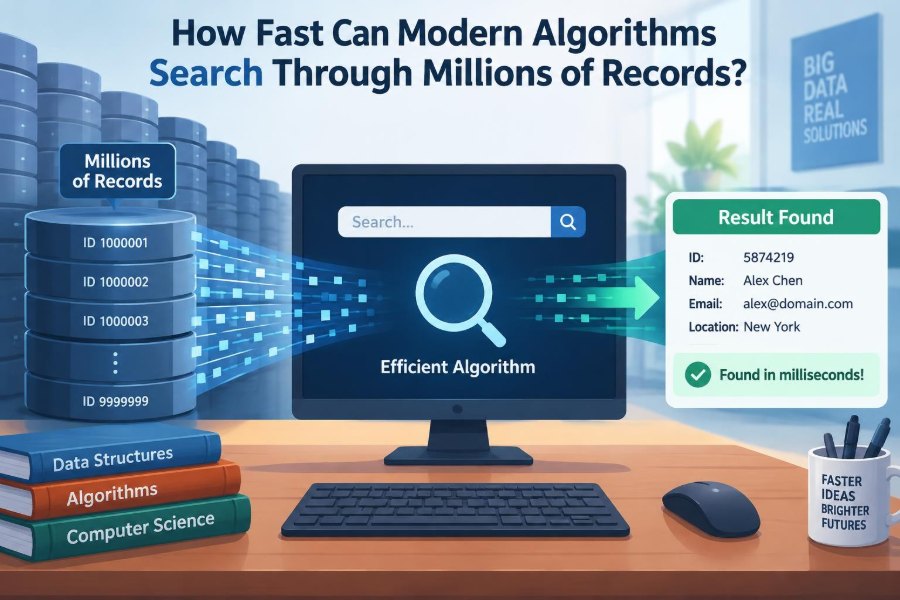

You type a name into a contacts app, look up an order number, search a product catalog, or filter a spreadsheet with hundreds of thousands of rows. The result often appears so quickly that it feels instantaneous.
Behind that simple experience is a practical computer science question: how does a program find one useful record among millions without checking every record one by one?
The answer is not one universal speed. It depends on how the data is stored, what kind of question is being asked, how much memory is available, and whether the data has been prepared in advance for searching.
Understanding these trade-offs makes performance less mysterious. It also helps students choose algorithms wisely and helps professionals recognize when a slow system needs a better data structure rather than a faster server.
🔎 What Does “Search” Actually Mean?
Searching means locating data that meets a condition. Sometimes the goal is to find one exact item, such as a customer with ID 48291. Other times it is to find every item matching a word, date range, category, or combination of filters.
Those tasks may all look like “search” to a user, but they can require very different algorithms. Exact lookup is usually simpler than asking for products whose descriptions contain several words or transactions within a changing set of rules.
📚 Why Millions of Records Change the Problem
With ten records, almost any approach feels fast. A program can inspect each item in sequence, and the delay is too small to notice.
At one million records, unnecessary work becomes visible. If a system checks records one at a time, the amount of work grows directly with the collection size. An approach that examines only a few dozen carefully chosen locations can be dramatically more practical.
The key question is not merely “How fast is the computer?” It is how much work does the algorithm make the computer do?
⏱️ The Difference Between Latency and Throughput
Latency is the time one search takes from request to answer. A person waiting for an autocomplete suggestion cares mostly about latency.
Throughput is how many searches a system can complete in a period of time. A reporting service handling many users may tolerate a modest delay for one query but still need to process a large volume of them.
A design that improves one does not automatically improve the other. Caching, parallel workers, and batching can increase throughput, while a well-chosen index often reduces latency.
📈 Big O Gives a Growth Pattern, Not a Stopwatch
Big O notation describes how an algorithm’s work tends to grow as the input grows. It is a useful model for comparing strategies, not a guarantee of a particular number of milliseconds.
Hardware, programming language, data layout, network delays, and the records themselves all affect observed time. Still, growth patterns reveal why some methods remain comfortable at large scale while others become expensive.
| Method | Typical growth for one lookup | Main requirement |
|---|---|---|
| Linear search | O(n) | No special ordering |
| Binary search | O(log n) | Sorted data |
| Hash table lookup | Usually O(1) | A useful hash-based index |
| Balanced tree lookup | O(log n) | Ordered tree index |
The notation describes the dominant trend. Two O(n) programs can still have very different real-world performance.
🚶 Linear Search: Looking at Records One by One
A linear search starts at one end of a collection and compares each item until it finds a match or reaches the end. Looking for a specific line in an unsorted paper list is the everyday analogy.
For an exact match, the desired record might appear early, late, or not at all. In the worst case, the algorithm inspects every record. This is O(n).
Linear search is not a mistake by definition. It works well for small collections, one-off tasks, streams of data, and searches based on conditions that have no available index.
📐 Binary Search: Halving the Search Space
Binary search works on sorted data. It checks the middle item, determines whether the target belongs before or after it, and discards half of the remaining possibilities.
If a list has roughly one million sorted entries, repeatedly halving it reaches a single candidate in about twenty comparisons. That is the power of logarithmic growth: each decision eliminates a large portion of the problem.
Its limitation is essential: the records must be sorted according to the field being searched. A list sorted by last name does not directly support binary search by account number.
🗂️ Sorting Is Useful but Not Free
Sorting a large collection takes work, commonly O(n log n) with general-purpose comparison sorting. If data changes frequently, maintaining sorted order also has a cost.
Sorting is worthwhile when many searches will follow, especially range queries such as “show orders placed between these two dates.” It may be wasteful when data is searched once and then discarded.
This is a recurring theme in system design: preparation can make repeated questions cheaper.
🔑 Hash Tables and Near-Constant-Time Lookup
A hash table uses a hash function to transform a key, such as an email address or product code, into a location or bucket. The program then checks a small relevant area instead of the whole collection.
Under typical conditions, an exact lookup has average O(1) behavior. In practical terms, the expected amount of lookup work does not grow much simply because the table holds more records.
That makes hash tables excellent for questions like “Does this username exist?” or “Get the record for this ID.” They are common in application code, caches, and database internals.
🧩 Hash Collisions Still Need Handling
Different keys can sometimes produce the same hash location. This is called a collision. A correct hash table must store and distinguish the colliding entries rather than assuming the hash itself is unique.
Collision handling may use linked groups, probing for another slot, or related techniques. Good hash functions and a sensible amount of unused table space keep collisions manageable in normal use.
Average O(1) does not mean every possible lookup is exactly constant-time. Poorly distributed keys, adversarial inputs, or an overloaded table can make operations slower.
🌳 Tree Indexes Preserve Order
Balanced search trees organize keys so that a lookup travels from a root through a small number of branches. Well-balanced trees provide O(log n) lookup, insertion, and deletion.
Unlike a basic hash table, a tree keeps keys in order. That makes it useful for range questions: find all invoice numbers from one value to another, or all timestamps within a time interval.
Database systems often use tree-like indexes designed for storage devices, especially B-trees and related structures. They reduce the number of expensive storage pages that must be read.
🧱 Why Database Indexes Matter So Much
A database index is a separate structure that maps searchable values to the rows or locations that contain them. It is similar to the index at the back of a textbook: you do not read every page to find a topic.
Without a suitable index, a database may perform a table scan, examining many or all rows. With a suitable index, it can often locate a much smaller set of candidates first.
An index is not magic. The database optimizer must decide whether using it is actually cheaper than scanning the table, based on the query and estimated number of matches.
⚖️ Indexes Trade Faster Reads for Other Costs
Every index occupies storage and must be updated when indexed values are inserted, changed, or removed. A table with many indexes can be fast to query but slower to write.
Indexes should support real access patterns rather than every field that happens to exist. Indexing a rarely queried column can add maintenance cost without providing meaningful benefit.
- Index fields commonly used in joins, filters, and sorting.
- Consider combinations of fields used together in frequent queries.
- Review indexes as application behavior changes.
- Measure queries rather than relying on assumptions.
🧭 Composite Indexes Depend on Column Order
A composite index contains more than one field, such as (department, hire_date). It can efficiently support searches that begin with the leading field and may support sorting or filtering by the later field as well.
Column order matters. An index beginning with department is naturally useful for “employees in this department,” but it may not efficiently serve a query that asks only for a date across every department.
Choosing composite indexes requires examining the actual query shapes, not just listing columns that sound relevant.
🧾 Exact Matches and Range Searches Need Different Tools
Exact-match questions generally favor hash-based lookup or a tree index. Range questions need an ordering, so tree-like indexes are often more appropriate.
For example, “find order 9132” is an exact match. “Find orders between Monday and Friday” is a range query. A hash table cannot naturally walk through neighboring date values in sorted order.
The fastest structure is therefore tied to the question. There is no single best data structure for all searches.
🔤 Text Search Is More Than Matching a String
Searching article titles, product descriptions, or documents becomes difficult when users expect word matching, stemming, phrase queries, typo tolerance, and relevance ranking.
Search engines commonly build an inverted index: a structure that maps terms to the documents containing them. Instead of scanning every document for the word “algorithm,” the system can retrieve the list associated with that term.
Extra features add complexity. Searching for “running” may need to consider “run,” while typo-tolerant search must consider near matches without producing too many irrelevant results.
🧠 Relevance Ranking Adds Work After Retrieval
Finding documents containing a word is only part of web-style search. The system also needs to rank candidates according to signals such as term frequency, field importance, recency, or application-specific quality rules.
A useful design often separates retrieval from ranking. First, an index narrows millions of documents to a manageable candidate set. Then more detailed scoring is applied to those candidates.
This staged approach avoids performing expensive analysis on every record for every query.
💾 Memory Searches and Disk Searches Behave Differently
Data already in memory can usually be accessed far more quickly than data that must be retrieved from persistent storage. This is why a theoretical count of comparisons is not the full performance story.
Storage is commonly read in blocks or pages, not as isolated bytes. Structures that keep related information together can reduce the number of page reads, which is especially valuable for large datasets.
Modern solid-state storage is fast, but memory access and storage access still have different costs. Database index designs account for this distinction.
🧊 Caching Avoids Repeating Familiar Work
A cache stores recently or frequently used results in a faster location, often memory. If many users request the same product details, a cache may answer without querying the main database each time.
Caching can make a popular search feel extremely quick, but it introduces a correctness question: when the original data changes, when should the cached version expire or be replaced?
Use caching for repeated, safely reusable work. Do not treat it as a substitute for an inefficient query that is usually unique.
🌐 Network Time Can Dominate the Algorithm
A search service may have an excellent O(log n) index and still feel slow if the request crosses several network services, waits in a queue, or transfers a large response.
For remote systems, total response time includes connection overhead, serialization, authentication, database access, computation, and response transfer. Optimizing only the inner search may produce little visible improvement.
A practical performance investigation follows the whole request path rather than guessing that the algorithm is always the bottleneck.
👥 Many Users Create a Different Scaling Challenge
One query against a million records might be fast, while thousands of simultaneous queries can exhaust CPU, memory, connection pools, or storage bandwidth. Concurrency changes the problem.
Systems address this with techniques such as read replicas, partitioning, queues, rate limits, and carefully managed pools of worker threads or database connections. Each option introduces operational complexity.
Fast individual searches are necessary, but capacity planning also asks how the system behaves during normal peaks and unexpected bursts.
🪓 Partitioning Narrows Where to Look
Partitioning divides data into smaller pieces based on a rule, such as date, customer region, or a range of IDs. A query that includes the partition key may need to inspect only one partition.
For instance, an archive organized by month can make a query for a recent month avoid older partitions. But a query across all months may still need to visit many of them.
A poor partition key can create hotspots, where one partition receives most writes or requests. Distribution rules should reflect real workload patterns.
🔀 Parallel Search Helps Only When Work Can Be Split
Several processors or machines can search different pieces of a dataset simultaneously. This can reduce elapsed time for tasks such as scanning independent partitions or processing large analytical queries.
Parallelism has overhead: splitting work, coordinating workers, moving data, and combining results all take time. A tiny lookup may be slower if it is needlessly distributed.
The benefit is strongest when the task is large enough and the parts can proceed with limited coordination.
📊 Selectivity Determines Whether an Index Helps
Selectivity describes how much a condition narrows the data. Searching for a unique account ID is highly selective because it usually identifies one record. Searching for a common status such as “active” may match most rows.
If a query will return a large portion of a table, scanning may be cheaper than bouncing between an index and many separate row locations. This is one reason database systems do not blindly use indexes.
Good query planning depends on both the structure of an index and the expected number of matches.
🧪 Measure Real Queries Instead of Guessing
Performance intuition is useful, but measurement catches surprises. Use representative data volumes, realistic query parameters, and the same kinds of concurrent access the production system will face.
Database query plans can reveal whether the system uses an index, scans a table, sorts large intermediate results, or performs an expensive join. Application profiling can expose repeated transformations or unnecessary network calls.
Test warm and cold conditions when relevant. A cached result and a first-time storage read can tell very different stories.
🛠️ A Practical Search Optimization Workflow
- Define the user-visible requirement: exact lookup, filtering, range search, text search, or analysis.
- Measure the current end-to-end response time and resource use.
- Inspect the query plan or program profile to find the actual expensive step.
- Choose a fitting structure, index, query rewrite, cache, or data layout improvement.
- Test correctness and performance with realistic data and concurrent load.
- Monitor after deployment because data distribution and traffic change.
This process avoids premature optimization, where developers complicate code before establishing that a meaningful problem exists.
⚠️ Common Mistakes When Chasing Search Speed
A frequent mistake is loading far more data than the screen needs. Asking for every matching row when the user needs the first page wastes database work, memory, and network bandwidth.
Another is applying functions to indexed fields in a filter, which can prevent straightforward index use depending on the database and expression. Storing inconsistent data types can also force conversions and complicate comparisons.
Finally, do not confuse a fast query with a good experience. A query may be quick while application code slowly formats thousands of results that no user will read.
🧮 Algorithmic Complexity Is Not the Whole Story
Big O helps identify dangerous growth patterns, but constants and hardware behavior matter. A linear scan over compact, contiguous memory can be surprisingly efficient for a modest dataset because modern processors handle predictable access well.
Conversely, a theoretically efficient structure can suffer from scattered memory access, poor cache behavior, or costly synchronization. Complexity analysis should guide design; benchmarking should validate it.
The mature perspective is not “always use O(1).” It is “choose the right trade-off for the data, operations, and environment.”
🎯 Choosing a Search Strategy by Use Case
Use a simple scan when data is small, temporary, or cannot be indexed usefully. Use sorted arrays or tree indexes when ordered traversal and ranges matter. Use hash tables for frequent exact key lookups.
Use database indexes for persistent structured records, and use specialized inverted indexes for rich text. Add caching when repeated requests justify the complexity, and partition only when one dataset or workload truly needs to be divided.
These choices can coexist. A commerce platform might use a database index for orders, a cache for popular product pages, and a dedicated text index for catalog search.
🏁 The Core Principle: Reduce Unnecessary Work
Modern systems can search millions of records quickly because they rarely treat every search as a request to inspect every record. They organize data so that a question rules out most possibilities early.
Sorting supports repeated halving. Hashing points toward likely locations. Tree indexes preserve order for ranges. Inverted indexes turn document search into list retrieval, while caches avoid work that has already been done.
The real measure of a fast search is not the size of the dataset alone, but how effectively the system narrows the path to the answer.
A million records is not automatically a performance problem. With an appropriate algorithm, a well-designed index, realistic measurement, and attention to the whole system, large-scale search becomes a manageable engineering task. 🔎💻📚