
A product team exports millions of orders for a quarterly report. A search service needs its results ranked before they appear on a screen. A data engineer prepares logs for analysis and discovers that a task as ordinary as “put these records in order” is consuming far more time than expected.
Sorting is one of the most familiar operations in computing, yet its cost changes dramatically as data grows. An approach that feels instant for a few thousand values can become impractical for hundreds of millions of records.
The difficult question is not simply which algorithm is fastest. Real running time depends on the kind of data, available memory, storage hardware, number of processor cores, and whether the data can fit in memory at all.
Understanding those trade-offs helps students reason about algorithms and helps professionals avoid expensive design mistakes. Here is how to estimate what different sorting algorithms can realistically do with huge datasets.
🧭 What “How Long” Really Means
There is no universal number of seconds for sorting a huge dataset. A runtime depends on the input size, the machine, the programming language and runtime, the record format, and the algorithm’s implementation.
A list of 100 million small integers is very different from 100 million customer records with long text fields. Comparing two records may require only one CPU instruction in the first case, while the second may involve multiple memory accesses and string comparisons.
For that reason, algorithm analysis usually begins with growth rate: how the amount of work rises when the number of items, usually written as n, rises.
📈 Why Dataset Size Changes Everything
Suppose a task grows proportionally with n. Doubling the dataset roughly doubles the work. That is manageable.
But if a task grows with n², doubling the dataset roughly quadruples the work. An algorithm that performs acceptably on 10,000 items can become enormously slower at 10 million items.
Huge datasets also cross physical boundaries. They may exceed CPU cache, then RAM, then the storage of one machine. Each boundary introduces a slower kind of data access, often changing which algorithm is practical.
🔢 Big-O Notation Is a Map, Not a Stopwatch
Big-O notation describes an upper-bound growth pattern as input becomes large. It is useful for eliminating poor choices early, but it does not directly predict elapsed time.
Two algorithms with the same O(n log n) complexity can differ substantially in practice. One may make fewer comparisons, use memory more efficiently, or cooperate better with the processor’s cache.
Likewise, an O(n²) algorithm can beat an O(n log n) algorithm on a tiny list because it has less setup overhead. Big-O answers “how does this scale?” rather than “will this finish in 4.2 seconds?”
🧮 The Sorting Complexity Landscape
| Algorithm family | Typical time complexity | Extra memory | Best fit |
|---|---|---|---|
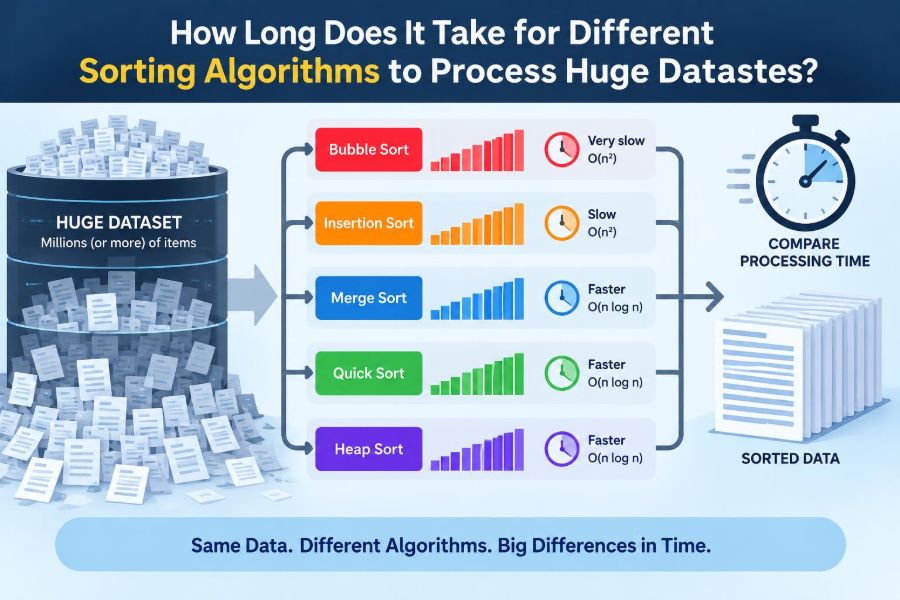
| Bubble, selection, insertion | Usually O(n²) | O(1) | Small or nearly sorted inputs |
| Quicksort | Average O(n log n) | Usually low | Fast in-memory general sorting |
| Mergesort | O(n log n) | Usually O(n) | Stable sorting and external sorting |
| Heapsort | O(n log n) | O(1) | Low-memory worst-case guarantee |
| Counting, radix, bucket | Often near O(n) | Depends on key range | Specialized numeric or fixed-format keys |
These categories provide a starting point, not a final decision. Properties such as stability, input order, and disk access may matter as much as the headline complexity.
🐌 Why Quadratic Sorts Collapse at Scale
Bubble sort, selection sort, and the basic version of insertion sort can examine pairs of items repeatedly. Their work commonly approaches n × n comparisons or moves.
With one million items, n² is already one trillion. Even if a machine can perform many operations quickly, real comparisons, branches, and memory access make that amount of work unsuitable for routine large-scale sorting.
These algorithms remain educationally valuable because their logic is easy to trace. In production, they are usually limited to tiny inputs or carefully chosen special cases.
🧩 When Insertion Sort Still Makes Sense
Insertion sort has an important exception: it performs very well when data is already nearly sorted. It can shift a small number of misplaced items rather than rebuilding the order from scratch.
This is why high-quality library sorts may use insertion sort for small partitions created by a faster algorithm. Its simple inner loop and low overhead can outperform more elaborate methods on short runs.
The lesson is not that insertion sort scales to huge datasets. It is that the shape of the input matters, and hybrid algorithms exploit that fact.
⚡ Quicksort and Its Average-Case Speed
Quicksort selects a pivot, divides items into those before and after it, and recursively sorts the resulting partitions. A reasonably balanced sequence of partitions yields average O(n log n) work.
It is often very fast in memory because partitioning can be done with compact loops and good locality. Many implementations sort in place or need only a small amount of additional stack memory.
For large arrays of primitive values, a well-engineered quicksort variant can be an excellent choice. The word “variant” matters: pivot selection and partitioning details strongly affect its behavior.
⚠️ Quicksort’s Bad Case
If quicksort repeatedly chooses a poor pivot, such as an extreme smallest or largest value, partitions can become badly unbalanced. Its work can then degrade to O(n²).
Already ordered data can trigger this behavior in simplistic implementations that always choose the first or last element as the pivot. Duplicate-heavy data can also be troublesome without a partitioning strategy designed for equal keys.
Modern implementations reduce this risk with sampled or randomized pivots, three-way partitioning, and fallback methods. Still, a worst-case guarantee may matter for services that must keep latency predictable.
🔀 Mergesort’s Predictable Work
Mergesort splits a sequence into halves, sorts each half, and merges the ordered results. Its running time is O(n log n) in the best, average, and worst cases.
That predictability is useful when input order is unknown or adversarial. Merging is also sequential: it reads ordered ranges from left to right, a pattern that works especially well when data comes from storage rather than RAM.
Traditional array mergesort generally needs another array for temporary output. On a huge in-memory dataset, that extra memory can be the deciding drawback.
📌 Why Stable Sorting Can Be Required
A sorting algorithm is stable when records with equal keys retain their previous relative order. Suppose transactions are first sorted by time, then stably sorted by account. Transactions inside each account remain time-ordered.
Mergesort is naturally stable when implemented carefully. Some library sorting functions are stable, while others are not, so developers should check the documented behavior instead of assuming.
Stability does not make a sort faster. It prevents accidental loss of meaningful earlier ordering and can simplify multi-key sorting pipelines.
🏗️ Heapsort and the Memory Trade-Off
Heapsort builds a heap, a tree-like arrangement where the next largest or smallest element can be efficiently removed. It guarantees O(n log n) time and uses O(1) auxiliary memory for an array implementation.
That combination is attractive when spare RAM is tight and worst-case performance matters. However, heapsort often performs less well in practice than quicksort or mergesort because its memory access pattern is less cache-friendly.
It is a sound tool when its guarantees fit the constraint, not a universal replacement for other O(n log n) methods.
🧠 CPU Cache Can Beat a Better-Looking Formula
Processors retrieve nearby memory much more efficiently than scattered locations. This behavior is called cache locality. Algorithms that scan arrays sequentially often benefit from it.
Two methods may both be O(n log n), yet the one with predictable contiguous access can finish sooner. Pointer-heavy structures, indirect comparisons, and cache misses can make theoretically modest work expensive.
This is one reason benchmarking the real record type matters. Sorting integers does not accurately model sorting large objects referenced through memory.
🧷 Comparison Cost Is Part of the Algorithm
Text strings, locale-aware names, version numbers, and compound keys are not equally cheap to compare. A sort with n log n comparisons may spend most of its time inside the comparison function.
For example, sorting records by a computed value is inefficient if that value is recalculated every time two records are compared. A common remedy is to calculate the sort key once, store it with the record, sort by that key, and then discard it if needed.
This technique is often called decorating records with keys. It trades additional memory for less repeated computation.
🔟 Counting Sort and Bounded Integer Keys
Counting sort does not compare every pair of values. Instead, it counts how often each key occurs and uses those counts to place values in order.
Its time is O(n + k), where k is the possible key range. If sorting exam scores from 0 to 100, k is small, and counting sort can be remarkably efficient even for a large number of scores.
If the keys are arbitrary 64-bit identifiers spread across an enormous range, allocating a count for every possible value is impossible. The key range, not merely the number of records, determines whether this method fits.
🪜 Radix Sort for Fixed-Format Data
Radix sort processes keys one digit or byte group at a time. It is often useful for fixed-width integers, dates in sortable numeric forms, or fixed-length identifiers.
Rather than comparing whole keys repeatedly, it distributes records into groups based on portions of a key. With a limited number of passes, its running time can be close to linear in the number of records.
Radix sort can be exceptionally fast in the right setting, but it needs extra buffers and careful handling of formats, signed values, and variable-length strings. It is specialized rather than universally superior.
🪣 Bucket Sort Depends on Distribution
Bucket sort divides values into ranges, sorts each bucket, and joins them. It can work well when values are distributed relatively evenly across a known interval.
Consider hypothetical sensor readings normalized between 0 and 1. Values can be assigned to range buckets, leaving smaller local sorting jobs. If nearly all values land in one bucket, the expected advantage disappears.
Distribution assumptions should be tested against actual data, including unusual but valid input. A method optimized for average traffic may behave poorly during an unexpected data surge.
💾 When the Dataset No Longer Fits in RAM
Once data exceeds memory, the primary problem is no longer just CPU comparisons. Storage reads and writes become a major cost, especially when access is random rather than sequential.
Trying to load everything into memory can trigger paging, where the operating system moves memory pages between RAM and storage. Heavy paging can slow a sort dramatically and make timing erratic.
At this scale, the practical question becomes: how can the system read and write large blocks efficiently while keeping memory use bounded?
📚 External Merge Sort for Massive Files
External sorting commonly uses external merge sort. First, the system reads a memory-sized chunk, sorts it in RAM, and writes that ordered chunk back as a temporary run. It repeats until the input becomes many sorted runs.
Next, it merges runs while reading buffered blocks from each one. Because the runs are already ordered, the system can produce one sorted output stream without loading all records at once.
The total duration depends heavily on storage throughput, number of merge passes, temporary-space availability, and record size. On storage-bound jobs, reducing data movement can matter more than reducing comparisons.
🗂️ Choosing Chunk Size and Merge Fan-In
A larger initial chunk creates fewer sorted runs, which can reduce later merging. But it must leave room for input buffers, output buffers, application overhead, and the operating system.
The number of runs merged at once is called the fan-in. A larger fan-in can reduce merge passes but requires more open files and buffers. Too many small buffers can hurt efficient sequential reading.
There is no single ideal setting. Production systems generally tune these choices according to memory limits, storage performance, file descriptor limits, and observed workload behavior.
🌐 Distributed Sorting Adds Network Costs
For data spread across a cluster, sorting usually involves partitioning records by key range, sending partitions to the machines responsible for them, sorting locally, and producing ordered partitions.
This shuffle phase can move a large volume of data over the network. A fast local sort does not help much if a skewed key range sends most records to one overloaded machine.
Distributed frameworks address this with sampling, partition boundaries, replication strategies, and retry handling. The overall duration includes coordination and data transfer, not only algorithmic sorting time.
⚖️ Data Skew Creates Stragglers
Data skew occurs when some keys or ranges appear far more often than others. A partition intended to be one of many equal jobs may become much larger than the rest.
In a distributed job, the slowest worker often determines completion time. This worker is called a straggler, and it may be slowed by an oversized partition rather than a weak processor.
Inspecting key distributions before choosing partitions is a practical defense. Where permitted by the application, splitting very common keys or using more refined range boundaries can restore balance.
⏱️ Throughput, Latency, and Batch Windows
A batch job sorting a nightly archive is judged mainly by throughput: how much data it processes over a long interval. A user-facing feature that sorts a page of search results is judged by latency: how quickly one request finishes.
These goals can favor different designs. A robust external merge sort may be appropriate for a large batch, while a service may avoid sorting the entire corpus at request time by maintaining indexes or retrieving only the top results.
Always define the operational requirement. “Fast” could mean finishing before morning, keeping a request responsive, or minimizing cloud resource consumption.
📏 How to Estimate Runtime Without Guesswork
Start by measuring a representative sample, not a toy input. Preserve realistic key lengths, duplicate rates, record sizes, and initial ordering.
- Measure the elapsed time and peak memory for a known input size.
- Increase the size gradually and observe whether the growth resembles the expected complexity.
- Track CPU use, disk reads and writes, and network transfer where relevant.
- Repeat with warm and cold storage conditions when storage is involved.
- Leave safety margin for concurrent workloads and unusual valid inputs.
A sample-based projection is still an estimate. It becomes less reliable when the larger test crosses a memory or storage boundary, so test beyond those thresholds whenever possible.
🧪 Benchmark the Whole Pipeline
A sorting benchmark that times only the sorting call may hide expensive work: parsing files, converting formats, generating keys, allocating objects, writing output, and validating results.
Measure both the inner sort and the end-to-end pipeline. If parsing consumes most of the job, replacing quicksort with another comparison sort may produce little noticeable improvement.
Correctness belongs in the benchmark too. Verify that output is ordered, all records are present, duplicates are handled correctly, and stability is preserved when the application requires it.
🛠️ Library Sorts Are Usually the Starting Point
Standard library sorting functions are generally heavily tested and often use hybrids that adapt to practical cases. They may switch strategies for small partitions, detect existing ordered runs, or protect against a known worst case.
Writing a custom sort is justified when the key format is specialized, memory and storage behavior must be controlled, or profiling identifies sorting as a real bottleneck. It is not justified merely because a textbook algorithm looks straightforward.
Before replacing a library function, check its stability, worst-case behavior, comparator requirements, and memory guarantees. Those details are part of the interface contract.
🚫 Common Mistakes With Huge Sorts
- Sorting more data than needed: use a top-k selection method when only the highest few results are required.
- Ignoring memory overhead: objects, pointers, temporary buffers, and keys can occupy much more space than raw values.
- Using a slow comparator: avoid repeated parsing or expensive transformations inside every comparison.
- Assuming average-case input: test ordered, reverse-ordered, duplicate-heavy, and skewed data.
- Forgetting I/O: an algorithm can be CPU-efficient but still slow because it repeatedly moves data to storage.
🎯 Sometimes You Do Not Need a Full Sort
If an application needs the ten largest values from a billion records, fully ordering all billion may be unnecessary. A bounded heap can keep only the best ten seen so far, using far less work and memory than a full sort.
Databases and search systems likewise rely on indexes, query planning, and partial ordering to avoid repeatedly sorting entire tables. The best optimization can be changing the question from “sort everything” to “retrieve exactly what the user needs.”
This does not remove the need for sorting everywhere, but it prevents a common architectural mistake: treating full ordering as the default operation.
🧱 Record Layout and Memory Pressure
Sorting large records directly can move substantial amounts of data. An alternative is to sort compact references or pairs containing a key and record position, then read records in that order when needed.
This reduces movement during comparisons, but it introduces indirection. If later access jumps randomly across storage, the apparent win may shrink. The right layout depends on whether the next stage scans records sequentially or accesses them individually.
Memory pressure also causes garbage collection or allocation overhead in some environments. Reusing buffers and choosing compact representations can improve a pipeline without changing the sorting algorithm.
🔒 Correctness and Operational Safety
A huge sort can fail halfway through because of full temporary storage, interrupted workers, malformed records, or a comparator that violates ordering rules. A comparator must be consistent: if A comes before B and B before C, it must not claim C comes before A.
External jobs need cleanup plans for temporary files and enough free space for intermediate output. Distributed jobs need repeatable tasks so failed work can be safely retried.
Performance planning should include these operational constraints. A fast method that cannot finish reliably is not a successful production design.
🧠 A Practical Selection Guide
Use the properties of the job to narrow the choice:
- For small or nearly sorted in-memory segments, insertion sort may be useful inside a hybrid.
- For general in-memory arrays, a high-quality library sort is usually the best first choice.
- For stable ordering or large sequential merges, mergesort-style approaches are strong candidates.
- For constrained memory and predictable O(n log n) behavior, consider heapsort or an introspective library sort.
- For bounded numeric keys or fixed-width formats, evaluate counting or radix sort.
- For datasets beyond RAM, use an external sorting design rather than forcing everything into memory.
Then validate the choice on representative data and the actual deployment hardware.
🏁 The Core Principle Behind Fast Large-Scale Sorting
Sorting huge datasets is not a contest won by memorizing one “best” algorithm. It is an engineering decision involving growth rate, input characteristics, memory limits, I/O patterns, reliability needs, and the actual result the system must produce.
Quadratic algorithms illustrate how rapidly poor scaling becomes unacceptable. O(n log n) comparison sorts provide dependable general-purpose performance, while counting and radix approaches can be faster when key constraints allow them. Once data exceeds RAM, efficient sequential I/O and merging become central.
The most useful habit is to combine algorithmic reasoning with measurement. Choose a plausible method, test it on representative data, locate the real bottleneck, and revise the design when the workload crosses a physical limit.
For huge datasets, the right sorting strategy is the one that matches the data, the hardware, and the real question—not simply the one with the most impressive name. 💻📊⚙️