
You enter a password, tap “Sign in,” and the website either lets you in or rejects you. Behind that ordinary moment, a system has to answer a delicate question: does this person know the right secret without the system itself needing to keep that secret in plain view?
Or consider a file download. A developer may need to know whether a large software package arrived intact, while a database needs to find a customer record among millions without reading every row. These look like different problems, but hashing is part of the solution to all of them.
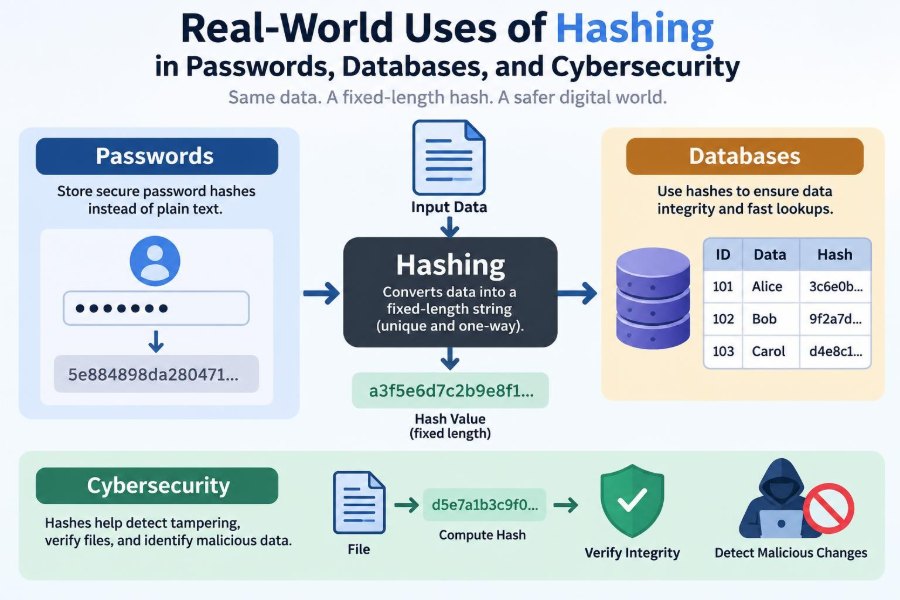
Hashing turns data into a fixed-size digital fingerprint. It is one of the most useful ideas in computer science because it supports fast lookup, integrity checks, secure password verification, and many cybersecurity workflows.
Its usefulness also creates confusion. A hash is not encryption, a checksum is not automatically secure, and a password hash can still be unsafe when it is designed poorly. Understanding the distinctions makes everyday systems much easier to evaluate.
🧩 What Hashing Actually Does
A hash function accepts input data of almost any length and produces an output of a fixed length called a hash value, digest, or fingerprint. The input may be a password, document, image, database key, or entire software archive.
For example, a hashing algorithm can turn a short word and a multi-gigabyte video into outputs with the same number of bits. The output is not a shortened copy of the input; it is the result of a mathematical transformation.
🔢 A Small Change Produces a Different Fingerprint
Strong hash functions are designed so that a tiny input change creates a dramatically different result. Changing Report.pdf by one character, or changing a single byte inside it, should produce a new digest that appears unrelated to the first.
This behavior is often called the avalanche effect. It makes hashes useful for detecting accidental corruption and unauthorized modification, because matching hashes provide evidence that two data inputs are the same.
🚫 Hashing Is Not Encryption
Encryption is intended to be reversible: an authorized party with the correct key can decrypt ciphertext and recover the original message. Hashing is generally intended to be one-way: it produces a digest, not a recoverable version of the input.
A company encrypting a customer address may need to read that address later. A service verifying a password only needs to test whether the submitted password produces the expected hash. Those requirements call for different tools.
| Technique | Main purpose | Can original data be recovered? |
|---|---|---|
| Hashing | Fingerprinting, verification, lookup | No, not from the hash alone |
| Encryption | Confidential storage or transmission | Yes, with the required key |
| Encoding | Representing data in another format | Yes, by decoding |
🔐 Why Password Systems Store Hashes
A well-designed login service should not need to store users’ actual passwords. At account creation, it processes the password with a password-hashing function and stores the resulting value, along with other needed parameters.
At login, it applies the same process to the submitted password and compares the result with the stored value. If they match, the service can authenticate the user without retrieving a plaintext password.
🧂 Salts Stop Identical Passwords Looking Identical
A salt is a unique, random value added to a password before hashing. It is normally stored alongside the password hash and does not need to be secret.
Without salts, two accounts using the same password would have the same hash. Salts ensure that their stored values differ, and they make large precomputed lookup collections far less useful against a stolen password database.
🐢 Password Hashing Should Be Deliberately Slow
For ordinary data integrity, speed is helpful. For passwords, speed helps attackers guess more candidates per second. That is why password storage should use algorithms built specifically for password hashing, such as Argon2, bcrypt, scrypt, or PBKDF2 with appropriate configuration.
These functions can require substantial time, memory, or both. A legitimate login experiences a small, acceptable delay; a large-scale guessing attempt becomes substantially more expensive.
⚠️ Why Fast General Hashes Are Poor Password Storage
Algorithms such as SHA-256 are valuable for integrity work, but a plain fast hash is usually unsuitable for password storage. Modern hardware can calculate enormous numbers of fast hashes, helping an attacker test guessed passwords efficiently after a breach.
Adding a salt to a fast hash improves the situation but does not replace a purpose-built password-hashing function. The key requirement is resistance to high-volume guessing, not merely producing a different-looking string.
🧠 Password Strength Still Matters
Password hashing reduces the damage caused by storing passwords, but it cannot make a weak password strong. If a user chooses a common or predictable password, an attacker may still guess it and test the guess against the stolen hash.
Long, unique passphrases and password managers address a different layer of the problem: the quality and reuse of the secret itself. Multi-factor authentication adds another barrier when a password is exposed.
🗃️ Hash Tables Make Data Retrieval Fast
In programming, hashing often means using a hash function to choose where a value belongs in a data structure called a hash table. A dictionary or map that connects a username to an account object is a familiar example.
Instead of scanning every stored entry, the program hashes the key and uses the result to select a likely location. Under good conditions, insertion and lookup are close to constant time on average.
🗺️ A Simple Hash Table Example
Imagine a library app storing book records by ISBN. It might hash an ISBN into one of many internal buckets, then search only the small group of entries in that bucket.
The exact internal position is not meaningful to the user. What matters is that the same key is handled consistently, allowing the app to locate its associated record quickly.
🚧 Collisions Are Normal, Not Necessarily Failures
A collision occurs when different inputs produce the same hash output or, in a hash table, map to the same bucket. Because a hash table has a limited number of buckets while possible keys are numerous, bucket collisions are unavoidable.
Programs manage them with strategies such as chaining, where a bucket holds multiple entries, or open addressing, where the program probes other positions. Good design keeps the number of collisions manageable.
🎯 Security Collisions Mean Something Different
In cryptography, a collision means finding two different inputs with the same digest. A cryptographic hash should make deliberately finding such a pair computationally impractical.
This is stricter than ordinary hash-table collision handling. A database map can safely resolve two keys in one bucket; a digitally signed document system may have serious problems if someone can intentionally create a different document with the same trusted digest.
📚 Database Indexes Can Use Hashing
Databases use indexes to avoid full-table scans. A hash index can be effective for equality questions such as “find the customer whose account number equals this value.”
Hash indexes are less naturally suited to range questions such as “show orders between these two dates,” because hashing does not preserve the original ordering. Tree-based indexes are often better for ordered searches, sorting, and ranges.
🔎 Exact Matching Versus Range Searching
Choosing an index follows the query pattern, not a rule that one structure is always faster. A system frequently looking up an exact session identifier may benefit from hashed lookup, while a reporting system filtering timestamps needs ordered access.
Developers should inspect their real queries, data distribution, and database engine behavior. An index that speeds one request can impose storage and update costs elsewhere.
🧱 Content Addressing Identifies Data by Its Hash
Some storage and version-control systems use a content hash as an identifier. If two files have exactly the same contents, they produce the same digest under the same algorithm and can be recognized as the same content.
This approach supports deduplication: a system can store one copy of identical content rather than many copies. It also helps detect whether stored content has changed.
🧾 File Integrity Checks Catch Corruption
Software publishers may provide a hash value for a download. After downloading, a user or installer can calculate the file’s hash and compare it with the published value. A mismatch signals that the file is not identical to the expected version.
This can reveal transfer errors, damaged storage, or tampering. However, the comparison is only trustworthy if the expected hash comes from a source the user can trust.
📦 Package Managers Verify Software
Package managers download libraries, updates, and tools from many locations. Hashes recorded in trusted metadata help them check that the downloaded archive matches the expected artifact before installation.
Hash verification protects integrity, but software supply-chain security often includes more: signature verification, trusted repositories, access controls, review processes, and prompt response to compromised credentials.
✍️ Digital Signatures Build on Hashing
Digital signatures commonly sign a hash of a message rather than the whole message directly. The signer uses a private key, and others use the corresponding public key to verify the signature and the message digest.
This provides stronger assurances than a bare hash published beside a file. If the signer’s key is trusted and protected, verification can connect the file to a particular signing identity while also detecting changes.
🌐 Message Authentication Uses Secret Keys
A hash alone is not proof of who created data. Anyone can calculate a hash of a message. A message authentication code, often an HMAC, combines a secret key with message data so that only parties holding the key can create a valid authenticator.
APIs use this pattern to verify that a request was generated by a party with the shared secret and was not altered in transit. Correct protocol design still matters, especially around timestamps, nonces, and replay protection.
🛡️ Hashing Helps Detect Tampering
Security tools can record hashes of important system files, configurations, or forensic evidence. Later calculations can be compared with the baseline to identify unexpected changes.
A changed hash does not automatically prove malicious activity. Legitimate updates, configuration changes, and file metadata behavior may be relevant. It is a strong signal for investigation, not a complete explanation by itself.
🧪 Malware Analysis Uses File Hashes Carefully
Analysts often use file hashes to refer precisely to a particular sample. If two copies have the same cryptographic hash, they are effectively the same byte-for-byte file for practical identification purposes.
But attackers can change a file slightly and produce a new hash, even if its behavior remains similar. Security teams therefore combine hashes with behavioral indicators, code analysis, domains, process activity, and other context.
🔗 Blockchains Chain Records with Hashes
In many blockchain designs, each block includes a hash connected to the previous block. Changing an earlier block changes its hash, which disrupts the links that follow it.
Hashing contributes tamper evidence, but it is not the whole security model. Consensus rules, network participation, key management, implementation quality, and incentives also affect how a blockchain system behaves.
🌳 Merkle Trees Verify Large Collections Efficiently
A Merkle tree is a tree structure built from hashes. It combines hashes of individual pieces into higher-level hashes until one top value, the Merkle root, represents the whole collection.
This lets a system prove that one item belongs to a large set without sending the entire set. Distributed systems, versioned data stores, and some blockchain systems use this idea to make verification more efficient.
🕵️ Privacy Risks of Hashing Personal Data
Hashing does not automatically anonymize personal information. Values from a small or predictable domain, such as a list of common email addresses or dates, can be guessed, hashed, and compared.
Unsalted hashes of identifiers can also become stable tracking tokens across datasets. Privacy-preserving designs may require access controls, minimization, encryption, keyed techniques, aggregation, or specialized privacy methods rather than simple hashing alone.
🧮 Encoding Often Gets Mistaken for Protection
Base64 strings can look scrambled, but Base64 is encoding, not hashing or encryption. Anyone can decode it without a secret key.
Similarly, a hexadecimal string may be the readable representation of a hash, but its appearance does not tell you whether the underlying algorithm is secure or whether it was used correctly. Always ask what process produced the value.
🔄 Algorithm Choice Must Evolve
Cryptographic practice changes as weaknesses are discovered and computing power improves. Older algorithms may remain usable for non-security checks in limited settings, but they should not be selected casually for adversarial security purposes.
Systems need an upgrade path. Password records can include an algorithm identifier and parameters, allowing a service to rehash a password with stronger settings after a successful login rather than forcing every account reset at once.
🛠️ Practical Rules for Developers
- Use a vetted library rather than implementing cryptographic algorithms yourself.
- Use a modern password-hashing function with unique random salts and adjustable cost settings.
- Use cryptographic hashes for integrity and security checks, not weak or obsolete alternatives.
- Compare sensitive authentication values with constant-time comparison functions when your platform provides them.
- Keep secrets such as HMAC keys outside source code and rotate them through a controlled process.
- Match database indexes to actual query patterns, then measure performance under realistic workloads.
👤 Practical Habits for Everyday Users
Users will not choose the hashing algorithm behind a service, but they can reduce the consequences of failures. Use a password manager to create unique passwords, enable multi-factor authentication where available, and install software from trusted channels.
When a reputable publisher provides a checksum and trustworthy instructions for verifying it, checking a high-value download can be worthwhile. Do not treat a hash copied from an untrusted page as proof that a file is safe.
🚨 Common Mistakes to Avoid
- Storing plaintext passwords or reversible password encryption when verification is all that is needed.
- Using one shared salt for every account, which weakens the benefits of per-user uniqueness.
- Calling a hash “encrypted data” and assuming it can be decoded later.
- Using a hash match as proof that a file is harmless or came from a trusted sender.
- Hashing personal data and assuming it has become anonymous.
- Building security decisions around an algorithm without considering keys, protocols, access, and implementation.
🧭 The Core Principle: Match the Hash to the Job
Hashing is a flexible building block, not one universal security spell. Fast non-cryptographic hashes help data structures; cryptographic hashes help detect modification; slow salted password hashes resist password guessing; keyed constructions authenticate messages.
The correct question is not simply “should we hash this?” It is “what property do we need: speed, integrity, secrecy, identity, privacy, or password resistance?” The answer determines the algorithm, surrounding controls, and limits of the design.
When hashing is matched to its real purpose and used with the right safeguards, it quietly makes everyday computing faster, safer, and easier to verify. 🔐🗃️💻