
You ask an AI coding assistant to build a feature: find duplicate customer records, rank search results, cache frequent requests, or process a large upload. Within seconds, it produces code that looks plausible and may even pass a few tests.
Then the real conditions arrive. The data set grows, requests become concurrent, memory use climbs, or one unusual input causes the service to slow down. Now the question is no longer “Can code be generated?” It is “Can you tell whether this is the right code?”
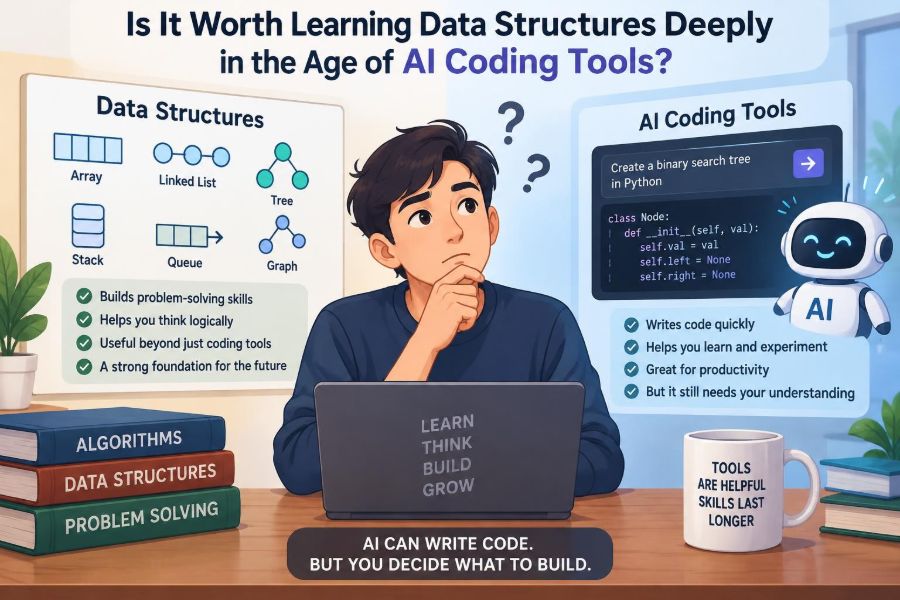
That question sits at the heart of learning data structures. AI coding tools can reduce the effort of writing implementations, but they do not remove the need to represent information well, reason about cost, or recognize a poor fit between a problem and a solution.
So, is deep study still worth the time for students and working professionals? Yes—but “deeply” should mean understanding the ideas well enough to make and evaluate decisions, not memorizing every textbook operation in isolation.
🧭 What “Learning Deeply” Actually Means
Learning data structures deeply does not mean reciting the code for a red-black tree from memory. It means understanding what a structure stores, what operations it makes efficient, what trade-offs it introduces, and when its assumptions fail.
A data structure is a deliberate way to organize data so particular operations become practical. An array favors indexed access. A hash table favors fast lookup by key. A queue favors first-in, first-out processing.
Deep knowledge lets you move from a requirement to a sensible model. You can also inspect generated code and ask the crucial follow-up: why this structure, under these constraints?
🤖 What AI Coding Tools Are Good At
Modern coding tools are useful partners for routine data-structure work. They can scaffold classes, suggest library methods, translate an approach between languages, and generate test cases for ordinary scenarios.
They are particularly helpful when you already know the intended design. For example, if you decide that a breadth-first search needs a queue and a visited set, an assistant can quickly produce a language-appropriate starting point.
They can also explain unfamiliar APIs. This reduces friction, but it changes where your attention should go: from typing mechanics toward design, verification, and system behavior.
⚠️ What Generated Code Cannot Reliably Decide
An AI tool sees a prompt and patterns from its training; it does not automatically possess complete knowledge of your production workload, latency target, data distribution, privacy constraints, or future maintenance needs.
It may choose a solution that is correct for a small example but costly at scale. It may also present code confidently while overlooking duplicate keys, malformed input, ordering requirements, or mutation shared across threads.
The key limitation is not that generated code is always wrong. It is that plausible code is not the same as justified code. Data-structure knowledge supplies the justification.
🧠 Data Structures Are Models of Real Problems
Many programming tasks become easier once you identify the shape of the information. A calendar of appointments has time intervals. A social network has relationships. A file system has hierarchy. A stream of support tickets has arrival order and priority.
Those shapes suggest different tools: interval-oriented representations, graphs, trees, queues, and priority queues. Choosing one is not merely an implementation detail; it determines what questions become cheap or expensive to answer.
AI can propose options, but you need enough conceptual vocabulary to recognize whether it modeled the problem correctly.
⏱️ Why Big-O Still Matters
Big-O notation describes how resource use grows as input size grows. It is not a stopwatch, and it does not predict every real-world performance detail. It is a way to compare growth patterns before a system is under stress.
Searching an unsorted list is typically linear, written as O(n). A hash table lookup is typically close to constant time on average, written as O(1), assuming a well-behaved hash function and controlled collisions.
The distinction matters when an operation occurs repeatedly. A small inefficiency inside a loop, request handler, or batch job can become the dominant cost as usage expands.
📈 Growth Matters More Than Tiny Benchmarks
Suppose a program checks whether each item in a list already appeared by scanning all previous items. This may feel fast for a dozen records. For a much larger input, repeated scans create quadratic work: roughly O(n²).
Using a set to track seen values usually changes the task to near-linear work, O(n) on average. The program is not just “a bit faster”; its growth pattern is fundamentally different.
Micro-benchmarks still have value, because constants, hardware, and language runtimes matter. But Big-O helps you avoid designs that become unreasonable before benchmarking even begins.
🗂️ Arrays and Dynamic Arrays: The Default Is Not Always Wrong
Arrays store elements in an ordered sequence and provide efficient access by position. Dynamic arrays, such as common built-in list types, can grow as items are added while retaining convenient indexed access.
They are excellent for collections you iterate through, display in order, or access by index. Appending is often efficient, although occasional resizing requires copying elements into a larger allocation.
The trade-off appears when inserting or removing near the front or middle. Elements after that position usually need to shift, so the operation takes linear time. That is often acceptable—until it happens frequently on large collections.
🔗 Linked Lists: Understand the Idea, Question the Default
A linked list stores each element in a node connected to the next node, and sometimes the previous one. Given a direct reference to a node, inserting or removing nearby nodes can be efficient.
But finding the node at position 50,000 still requires walking through earlier nodes. Linked lists also add pointer overhead and can use memory less efficiently than arrays in many practical environments.
They are valuable for understanding references and local updates. Yet “use a linked list for lots of insertions” is incomplete advice. You must ask where insertions occur and whether you already have the relevant node.
🔑 Hash Tables, Maps, and Sets
A hash table maps a key to a storage location using a hash function. Maps associate keys with values; sets track unique values. They are everyday tools for counting, caching, deduplication, and fast membership checks.
Consider processing event IDs and rejecting repeats. A set expresses the requirement directly: check whether the ID exists, then add it if it does not. A list can do the same job, but repeated membership checks are usually much more expensive.
Hash tables have limits. They may not preserve a useful order, consume extra memory, and depend on sensible equality and hashing rules. Their usual constant-time behavior is an average-case expectation, not a magical guarantee.
🌳 Trees Make Hierarchies and Ordered Search Possible
Trees represent parent-child relationships. Folders inside folders, document outlines, organization charts, and syntax structures are naturally tree-shaped rather than flat lists.
Search trees organize comparable values so that a search can discard much of the remaining data at each step when the tree stays balanced. Balanced variants are designed to avoid becoming a long, inefficient chain after unlucky insertion patterns.
You do not need to hand-implement every balancing rule for routine work. You do need to know when sorted lookup, range queries, or hierarchy suggests a tree-like structure rather than a hash table or array.
🕸️ Graphs Describe Connections, Not Just Collections
A graph contains vertices, often called nodes, and edges that describe connections. Roads between locations, prerequisites between courses, dependencies between services, and followers in a social platform can all be modeled as graphs.
Once you identify a graph, questions become clearer: Is there a path? What is the shortest path under a chosen cost? Which dependencies must happen first? Are there cycles that make an order impossible?
A generated answer may use a list because lists are easy to write. Recognizing the underlying graph prevents that simplification from hiding the actual problem.
🚦 Queues, Stacks, and Deques Encode Process Rules
Some structures are mainly about the order in which work is handled. A queue is first-in, first-out, making it useful for request processing and breadth-first traversal. A stack is last-in, first-out, useful for undo histories, nested parsing, and depth-first traversal.
A deque, or double-ended queue, supports efficient work at both ends. It can suit sliding-window algorithms, task scheduling, and situations where a normal array would repeatedly shift elements.
These choices communicate intent. When a reader sees a queue, they can immediately infer that arrival order matters.
🏁 Priority Queues Solve “What Should Happen Next?”
A priority queue removes the highest- or lowest-priority item rather than simply the oldest item. It is commonly implemented with a heap, a partially ordered tree-like structure.
Imagine a job system where urgent work should run before routine work, while jobs continue arriving. Sorting the entire list after every arrival is wasteful. A priority queue maintains the next best candidate efficiently.
This is a useful example of structural thinking: the requirement is not “keep everything completely sorted.” It is “repeatedly retrieve the most important next item.”
🧩 The Operation Mix Determines the Best Choice
There is no universally best data structure. The right choice depends on the operations that dominate your workload: lookup, insertion, deletion, traversal, sorting, membership testing, or range search.
| Primary need | Often useful choice | Question to verify |
|---|---|---|
| Fast lookup by unique key | Hash map | Do you need ordered traversal? |
| Ordered items with indexed access | Dynamic array | How often do middle insertions occur? |
| Repeated next-highest item | Priority queue | Do you need all items fully sorted? |
| Relationships and paths | Graph | Are edges directed or weighted? |
| Hierarchical nesting | Tree | Do nodes have one parent or many links? |
The table is a starting point, not a substitute for analysis. Data size, access patterns, memory constraints, and language libraries all affect the final decision.
🧪 Small Inputs Can Hide Structural Mistakes
Many tutorials and AI demonstrations operate on tiny collections. Under those conditions, nearly every reasonable approach looks acceptable, and an inefficient nested loop may finish instantly.
Production systems are different because work can repeat. A daily report may process years of records. A seemingly small endpoint may receive many requests at once. A loop inside a loop can become a recurring cost.
When reviewing code, ask what happens if the input becomes 100 times larger, or if the operation runs thousands of times. You do not need exact forecasts to spot risky growth.
🧱 Libraries Do Not Eliminate the Need for Concepts
Most professional code should use tested standard-library collections rather than custom implementations. This is usually safer, clearer, and more maintainable than writing your own hash map or balanced tree.
Using a library is not the same as understanding it. You should know whether a collection permits duplicates, preserves insertion order, has mutable keys, supports concurrent access, or makes removal expensive.
Think of libraries as reliable tools, not as replacements for judgment. You need not forge a hammer to understand when a hammer is unsuitable.
🔍 Reading AI Output Requires a Review Checklist
Before accepting generated data-structure code, review the design rather than only the syntax. A useful checklist turns vague doubt into specific questions.
- What operations are frequent, and what is their likely time cost?
- Does the chosen structure preserve required order, uniqueness, or priority?
- What happens with empty input, duplicates, missing keys, and very large input?
- Does the code mutate data that another part of the program relies on?
- Are memory use, concurrency, and error handling relevant here?
These questions are useful whether the code came from an AI assistant, a coworker, a tutorial, or your own keyboard.
🧯 Correctness Comes Before Optimization
A fast solution to the wrong problem is still wrong. Start by stating the required behavior in plain language and identifying edge cases before reaching for a sophisticated structure.
For example, “remove duplicates” could mean preserve first-seen order, preserve last-seen order, ignore case, merge records by an ID field, or simply return unique values in any order. Each interpretation can lead to a different implementation.
Data-structure knowledge supports correctness because it forces you to clarify what the program must retain: order, identity, relationships, multiplicity, or priority.
⚖️ Time Complexity Is Only One Trade-Off
Choosing a structure by Big-O alone can be misleading. Memory footprint, allocation behavior, cache locality, implementation complexity, and readability also matter.
For a small, bounded collection, a simple array scan may be clearer and entirely adequate. A hash table may use more memory than the application can comfortably afford in a high-volume process.
Good engineering means choosing the simplest design that meets real requirements with acceptable margins. “More advanced” is not automatically “better.”
🧵 Concurrency Adds Another Layer of Difficulty
When multiple threads or processes access shared data, the correct structure must also be used safely. A standard map may be perfectly suitable in single-threaded code but unsafe when simultaneous updates occur without coordination.
Locks, immutable snapshots, concurrent collections, message queues, and partitioned ownership are different strategies. Their suitability depends on how data is shared and how much contention the system can tolerate.
AI can suggest concurrency primitives, but generated code deserves extra scrutiny here. Bugs may appear only under timing conditions that basic tests do not reproduce.
🧾 Memory and Data Layout Are Practical Concerns
Every stored value has overhead beyond its visible contents. Object headers, references, unused capacity, hash-table buckets, and node links can matter when collections become large.
Data layout can also affect speed. Contiguous arrays often work well with modern hardware because nearby elements are stored close together. Pointer-heavy structures can require more scattered memory access.
You do not need hardware-level expertise for every application. Still, knowing that memory behavior exists helps you avoid assuming identical Big-O costs produce identical real performance.
🧭 Abstraction Choices Affect Maintenance
Representing a task with the right abstract type makes code easier to read and change. A Set says “uniqueness matters.” A Queue says “process in arrival order.” A Map says “find information by key.”
That clarity matters when requirements change. If a team later asks for priority handling, a queue-oriented design reveals exactly where a priority queue might belong. A vague array used for everything hides the rule inside ad hoc loops.
Data structures are therefore part of communication between developers, not just performance machinery.
🎯 Interviews Are Not the Only Reason to Learn Them
Technical interviews often emphasize arrays, trees, graphs, and complexity analysis. That can make data structures feel like a gatekeeping exercise detached from real work.
Interview-style puzzles are not identical to day-to-day engineering, but the underlying habits transfer: break down a problem, identify constraints, reason about growth, test edge cases, and explain trade-offs.
Do not study only to memorize puzzle patterns. Use problems as practice in selecting representations and defending choices.
🛠️ A Practical Depth Level for Most Developers
Most developers should confidently understand arrays, strings, maps, sets, stacks, queues, heaps, trees, graphs, recursion, iteration, and basic complexity analysis. They should be able to use standard implementations and explain common trade-offs.
Deeper specialization becomes valuable when your work involves algorithms, databases, compilers, search, distributed systems, performance-sensitive services, graphics, machine learning infrastructure, or systems programming.
You do not have to master every exotic structure before building useful software. Build a strong core, then go deeper where your domain repeatedly demands it.
📚 Learn Concepts Through Problems, Not Isolated Definitions
Reading definitions helps, but durable understanding comes from solving small, varied problems. Implement a recent-items list, a duplicate detector, a task scheduler, a dependency checker, and a shortest-route finder.
After each solution, explain why the chosen structure fits. Then deliberately try an alternative and identify what becomes slower, less clear, or harder to maintain.
This comparison builds intuition. It also makes AI assistance more valuable because you can ask for alternatives and evaluate them rather than accepting the first answer.
🧑💻 Use AI as a Tutor and Reviewer
AI tools can support learning without replacing the struggle that develops judgment. Ask the tool to explain the time and space complexity of your approach, generate edge cases, or compare two designs under stated assumptions.
Try writing a solution first. Then ask for a critique and look for disagreements. If it proposes a structure you do not know, request a small example and verify the explanation using your language’s documentation or a trusted reference.
A productive prompt is specific: “I need to preserve insertion order, reject duplicates, and process one million records in batches. Compare an ordered set with a map-plus-list design.” Constraints lead to better analysis.
🚫 Common Ways Learners Use AI Poorly
The biggest mistake is copying an answer before forming any model of the problem. You may get working code, but you lose the chance to notice why it works or where it will break.
Other unhelpful patterns include:
- Asking for “the most efficient” solution without describing input size or required behavior.
- Accepting complexity claims without checking hidden loops or library operations.
- Replacing a simple readable solution with an advanced structure that solves no real problem.
- Testing only the happy path supplied in the original prompt.
These habits create dependency. The remedy is not avoiding AI; it is retaining responsibility for the design.
✅ A Better Workflow for AI-Assisted Coding
- Describe the data, required outputs, and constraints in plain language.
- List the operations the program performs most often.
- Choose one or two candidate structures and state your reasoning.
- Use AI to draft, compare, or challenge the implementation.
- Test normal cases, boundaries, invalid input where relevant, and larger synthetic inputs.
- Review complexity, memory use, and readability before integrating the code.
This workflow is slower than blind copying for a five-line task, but it scales far better when code becomes consequential.
🔄 Refactoring Is Where Knowledge Pays Off
Existing code often begins with a simple list because it was easy to write. Later, a feature adds frequent lookups, unique constraints, prioritization, or relationship traversal. The original representation becomes a bottleneck or source of complexity.
Knowing data structures helps you refactor safely. You can separate concerns: maintain a list for display order, a map for lookup, and a set for membership instead of forcing one collection to perform every role poorly.
This is common professional work. The value is not only inventing an ideal design from scratch; it is recognizing when an old design no longer matches current behavior.
📏 Measure When the Stakes Justify It
Complexity analysis identifies likely risks, but measurement validates behavior in your environment. Profile a slow path, observe memory use, and test with data that resembles realistic usage where possible.
Be careful with conclusions from artificial benchmarks. A benchmark can accidentally measure setup time, logging, network delays, or a runtime warm-up rather than the data structure itself.
The healthy sequence is: reason first, measure second, then improve the bottleneck you actually found. This prevents both guesswork and premature optimization.
🌱 The Core Skill Is Judgment, Not Memorization
AI coding tools make implementation cheaper, which makes design judgment more visible rather than less relevant. Someone still has to define the problem, choose a representation, review assumptions, and decide whether the result is safe and maintainable.
Learn the foundational structures well enough to recognize their strengths and limits. Practice applying them to real patterns, use libraries intelligently, and let AI accelerate the parts it handles well.
The goal is not to compete with AI at producing boilerplate; it is to become the person who can tell which solution fits, why it fits, and when it needs to change.
Deep data-structure knowledge gives you that independence. Let AI help you write and explore, but keep the responsibility for understanding in your own hands. 💻🧠🚀