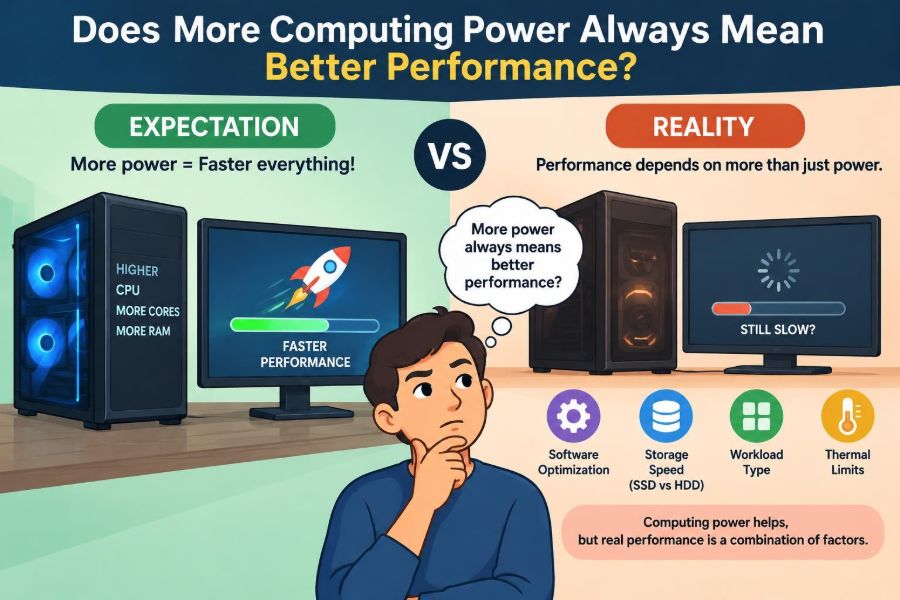

You replace an older laptop with a model that has a faster processor, more memory, and a newer graphics card. Yet the browser still pauses when many tabs are open, a video call stutters, or a spreadsheet takes too long to respond.
Or perhaps a team moves an application to a larger cloud server and expects it to become dramatically faster. The monthly bill rises, but users barely notice a difference.
These outcomes feel wrong because “more computing power” sounds like a simple promise: more power should mean more speed. Computing systems, however, are built from connected parts, and the slowest or most constrained part often shapes the experience.
Understanding that difference helps students reason about algorithms, helps professionals diagnose performance problems, and helps everyone make smarter hardware and software choices.
🧭 Performance Is More Than a Specification
Performance is how effectively a system completes a task under real conditions. It may mean finishing a calculation sooner, loading a page quickly, handling more users, reacting immediately to input, or using less battery.
A processor’s advertised speed is only one input. A useful performance question starts with the workload: what is slow, when does it become slow, and what resource is limiting it?
For example, a computer can compile code quickly but open large project files slowly. Compilation may be limited by CPU work, while opening files may be limited by storage access.
⚙️ Computing Power Has Several Meanings
“More power” can refer to several different resources. They do not substitute for one another perfectly, because programs use them in different ways.
- CPU capacity: instruction processing and general-purpose calculations.
- Memory capacity and bandwidth: how much active data fits in RAM and how quickly it moves.
- Storage performance: how fast files can be read and written.
- GPU capacity: graphics rendering and certain highly parallel calculations.
- Network capacity and latency: data transfer speed and communication delay.
Adding one resource helps only if that resource is relevant to the task. A faster GPU will not automatically fix a database query waiting on disk storage.
🚧 The Bottleneck Determines the Result
A bottleneck is the resource that most limits progress at a particular moment. Think of a road with six lanes that narrows to one lane before a bridge. Widening the road farther back does not remove the queue at the bridge.
In a program, the bottleneck might be one CPU core, an overloaded database, a slow network request, insufficient memory, or a lock that forces many threads to wait.
Finding the bottleneck is more valuable than guessing which component has the largest specification. It also explains why a hardware upgrade can produce a surprisingly small improvement.
📐 Amdahl’s Law Sets a Practical Limit
Amdahl’s Law expresses a simple constraint: speeding up one part of a task can only improve the whole task by the amount of time that part originally consumed.
Suppose, hypothetically, a program spends most of its time reading data from a remote service and only a small portion performing calculations. Making its CPU work much faster changes little because the waiting time remains.
This is not an argument against faster hardware. It is a reminder to improve the portion that dominates total time. The overall result is governed by the parts that cannot be accelerated, not just the part that can.
🧮 CPU Speed Is Not One Simple Number
Clock speed, measured in gigahertz, describes how rapidly a processor’s clock cycles. It does not by itself show how much useful work the processor completes per cycle.
Processor design, cache size, instruction types, branch prediction, core count, cooling limits, and the software itself all affect results. Two CPUs with similar clock speeds can perform quite differently on the same job.
Benchmark scores can be informative, but only when the benchmark resembles the work you actually do. A score for rendering may say little about a computer used mainly for documents, web applications, and video meetings.
🧵 More CPU Cores Need Parallel Work
A multi-core processor can run more than one stream of work at once. This is powerful for workloads that can be divided into largely independent pieces, such as rendering video frames, processing many images, or serving separate user requests.
But some work is inherently sequential. A later step may need the output of an earlier step, like following a recipe where the dough must be mixed before it can be baked.
Adding cores also creates coordination costs. Threads may compete for shared data, communicate results, or wait at synchronization points. More cores help most when a program is designed to use them well.
🧠 RAM Capacity Prevents Expensive Detours
Random-access memory, or RAM, holds data and programs currently in use. When enough RAM is available, the operating system can keep active information close to the CPU.
When memory becomes scarce, the system may move some data to storage and retrieve it later. This process, often called paging or swapping, can make an otherwise capable machine feel unresponsive because storage is far slower than RAM.
Extra RAM is therefore especially useful when the current workload genuinely runs out of memory: many browser tabs, large datasets, virtual machines, or media-editing projects. Unused RAM capacity alone does not make a task compute faster.
📚 Memory Bandwidth and Caches Matter Too
Capacity answers “how much can fit?” Memory bandwidth answers “how quickly can data be supplied?” Some scientific, data-processing, and graphics workloads move huge amounts of data and can be limited by this flow.
Processors also use small, fast memories called caches. A cache keeps recently used or nearby data close to the CPU. Programs that access data predictably often benefit because needed information is ready sooner.
Poor data access patterns can leave a powerful processor waiting for memory. This is why changing an algorithm’s data layout can sometimes improve performance without changing the computer at all.
💾 Storage Speed Changes Waiting, Not Every Task
Storage matters when software opens files, loads assets, saves projects, indexes data, or uses temporary files. Solid-state drives generally reduce access delays compared with older mechanical hard drives, especially for many small reads and writes.
Once a file is loaded and a calculation is entirely in memory, storage may no longer be the limiting factor. Installing a faster drive will not make a purely CPU-bound calculation proportionally faster.
Storage also has different patterns of performance. Sequentially reading one large video file differs from finding thousands of small files scattered across a file system.
🎮 A GPU Is Specialized, Not Universal
Graphics processing units, or GPUs, contain many smaller processing units designed for work that can be performed across many data elements at once. This makes them effective for graphics, image operations, simulations, and some machine-learning workloads.
However, GPU acceleration requires software support and a suitable problem. Moving data between system memory and a GPU can add overhead, and a task with many dependent steps may not parallelize effectively.
A stronger GPU can transform a supported rendering workflow while making virtually no difference to a text editor or a database operation whose main delay is network communication.
🌐 Networks Turn Distance Into Delay
For cloud services, web applications, multiplayer games, and remote desktops, the network may dominate the experience. Two related terms explain much of this: bandwidth is how much data can move per unit of time, while latency is the delay before a response begins.
A connection with high bandwidth can transfer a large download quickly but still feel sluggish if each interaction requires several round trips to a distant server. Faster local hardware cannot eliminate that travel time.
Reducing unnecessary requests, placing services closer to users, caching data, and designing efficient protocols can matter more than increasing a server’s CPU count.
🗄️ Databases Often Wait on Data Access
Applications frequently appear slow because of database work. A query may scan too many records, sort a large result, wait for a lock, or travel repeatedly between the application and database server.
Giving the application server more CPU can help if it is actually busy processing requests. It does not solve a query plan that retrieves far more data than needed.
Indexes, well-designed queries, appropriately sized result sets, and careful transaction design are common ways to address database bottlenecks. These changes must be tested, because an index that helps one workload can add write overhead to another.
🧩 Software Algorithms Can Outweigh Hardware
An algorithm is a method for solving a problem. Its growth in work as the input grows often matters more than a modest increase in hardware speed.
For instance, repeatedly checking every item against every other item can become costly as a list grows. Choosing a better data structure, such as a hash-based lookup where appropriate, may remove enormous amounts of repeated work.
Hardware buys capacity; algorithms reduce demand. The best improvement is often not “make the machine work harder,” but “stop asking it to do unnecessary work.”
🔁 Overhead Can Consume the Extra Capacity
Every system has overhead: work needed to manage other work. Examples include creating threads, copying data, encrypting requests, collecting garbage, scheduling tasks, logging events, and coordinating distributed services.
At small scale, this overhead may be barely visible. At larger scale, it can become a major share of execution time, especially when a design creates many tiny tasks or frequent communication.
A faster machine may process the useful work more quickly while leaving coordination costs unchanged. In some cases, more parallelism increases overhead enough that performance stops improving or even declines.
🔒 Contention Makes Fast Resources Wait
Contention occurs when multiple tasks need the same limited resource at the same time. That resource might be a database row, a shared memory structure, a disk, a network connection, or even a CPU cache.
Consider a checkout system where many requests try to update the same inventory record. More application servers can create more simultaneous attempts, but only one update may safely proceed at a time.
The solution may involve redesigning the shared work, batching updates, partitioning data, or using a different concurrency strategy. Simply increasing server power can amplify the pressure on the shared point.
📈 Throughput and Latency Tell Different Stories
Throughput is the amount of work completed over time, such as reports generated per hour. Latency is how long one task takes, such as the time for a user to receive a search result.
Adding workers can increase throughput because more tasks are completed concurrently. Yet individual latency can worsen if those workers overload a shared database or create a longer queue.
Good performance evaluation asks which measure matters. A nightly batch process may prioritize throughput, while an interactive form needs predictable low latency.
⏳ Queues Create Sudden Slowdowns
Systems often seem fine until demand nears a resource’s capacity. As requests arrive nearly as quickly as they can be processed, a queue forms. Even a small increase in incoming work can then cause much longer waits.
More computing power can raise capacity, which is useful. But it does not remove the underlying behavior: every finite service has a point where arrivals can exceed what it can process.
Queue management includes keeping utilization below dangerous levels, smoothing bursts, setting limits, prioritizing critical work, and giving users clear feedback rather than allowing requests to wait indefinitely.
🌡️ Thermal Limits Can Reduce Sustained Speed
Processors generate heat while working. If a device cannot dissipate that heat effectively, it may reduce clock speed to protect itself, a behavior commonly called thermal throttling.
This is why a device can feel quick for a short task but slow down during a long export, game session, or compilation. Thin designs, dust buildup, high ambient temperature, and constrained cooling can all affect sustained performance.
For long workloads, cooling design and power limits matter as much as peak specifications. Short benchmark bursts may not represent an hour of continuous work.
🔋 Power Budgets Shape Mobile Performance
Phones and laptops must balance performance against battery life, heat, and noise. Their operating systems and processors dynamically adjust power use based on demand, temperature, battery state, and the kind of work being performed.
This means a laptop on battery power may behave differently from the same laptop connected to power. Background activity can also compete for limited energy and thermal headroom.
Maximum performance is not always the right goal. For a traveler writing documents, lower power use and reliable battery life may be more valuable than a small gain in peak speed.
🧪 Benchmarks Need Context
Benchmarks measure performance under a defined test. They are useful for comparing systems only when their test conditions, software versions, power settings, and workload patterns are understood.
A synthetic benchmark may isolate one component very well, while a real-world benchmark may better represent an editing or development workflow. Neither is automatically “the true” performance number.
| Question | Why it matters |
|---|---|
| What workload was tested? | Different programs stress CPU, GPU, memory, storage, or networks differently. |
| Was performance sustained? | Short tests can hide thermal or power limits. |
| What was measured? | Throughput, latency, and responsiveness can lead to different conclusions. |
| What configuration was used? | Memory, storage, cooling, drivers, and settings can affect results. |
🖱️ Responsiveness Is Often About the Slowest Moment
People judge a system by interruptions: a frozen cursor, a delayed keystroke, a paused animation, or an application marked “not responding.” Average speed does not fully capture these experiences.
A program may complete background work efficiently but still feel poor if it blocks the interface while doing so. Keeping user-interface work separate from long-running tasks can improve perceived performance without changing total computation.
For interactive software, predictable response times are often more valuable than occasional bursts of exceptional speed.
🧹 Background Work Can Hide the Real Problem
Updates, cloud synchronization, antivirus scans, browser extensions, startup utilities, and backup software can consume CPU time, memory, storage activity, or network bandwidth. Their effect is most visible on systems with limited spare capacity.
It is tempting to blame the hardware immediately. Before upgrading, observe whether the slowdown occurs only during a particular background activity or after a specific application starts.
Disabling software blindly is not a sound solution, especially for security tools. The practical goal is to identify unnecessary work, schedule intensive tasks sensibly, and retain protections that are needed.
🔍 Measure Before You Upgrade
Performance tuning should begin with observation rather than assumptions. Operating-system monitoring tools can show processor utilization, memory pressure, disk activity, network use, and which applications are consuming resources.
Useful measurements include the duration of a repeatable task, responsiveness under normal load, error rates, queue length, and resource use over time. A single screenshot during one slow moment is a clue, not a complete diagnosis.
- Describe the exact task that feels slow.
- Reproduce it under similar conditions.
- Observe which resource is saturated or waiting.
- Form one testable hypothesis.
- Change one relevant factor and measure again.
This process prevents expensive upgrades that target the wrong component.
🛠️ Match the Fix to the Constraint
Once the likely constraint is known, choose a fix that addresses it directly. A balanced approach is usually more effective than maximizing one specification.
- If memory pressure is high, reduce active workloads or add RAM where the system supports it.
- If storage is continuously busy during file-heavy work, investigate drive health, free space, file patterns, and a faster storage option.
- If one CPU core is saturated, improve the algorithm or use carefully designed parallelism when possible.
- If requests wait on a database or network, optimize queries, caching, request patterns, or service placement.
- If heat limits long tasks, improve cooling conditions or select hardware designed for sustained loads.
Each change should be verified with the same workload that revealed the problem.
☁️ Cloud Scaling Has the Same Limits
Cloud platforms make it easy to add virtual CPUs, memory, or additional instances. This flexibility is valuable, but it does not bypass bottlenecks in application architecture.
Vertical scaling means giving one machine more resources. Horizontal scaling means adding more machines. Horizontal scaling can improve capacity for independent requests, but shared databases, session state, file storage, and coordination still require careful design.
Autoscaling can respond to demand, yet it may react too late to a sudden burst or add instances that all wait on the same downstream service. Capacity planning and load testing remain necessary.
💰 More Power Has Costs Beyond Purchase Price
Powerful hardware and larger cloud instances can cost more to buy, rent, cool, power, maintain, and replace. They can also encourage a pattern of postponing software improvements.
That does not make upgrades wasteful. Buying more capacity is sensible when demand is legitimate, deadlines matter, and the workload is known to benefit. The key is recognizing whether the improvement is temporary headroom or a durable solution.
A well-chosen upgrade supports good design; it should not be assumed to compensate for every inefficient design forever.
🧠 Common Assumptions That Mislead
Several intuitions are understandable but incomplete. “Higher clock speed always wins” ignores architecture and workload. “More cores always help” ignores sequential work and coordination. “More RAM always makes a computer faster” confuses avoiding memory shortages with speeding up all tasks.
Another common mistake is treating low average CPU usage as proof that the CPU cannot be involved. One busy core, a short burst, or time spent waiting on memory can still matter.
The broader lesson is to avoid diagnosing from one headline specification. Performance is an interaction among hardware, software, data, and demand.
🎯 Choosing Hardware for Real Work
Start with the applications and files you use, not a generic idea of “fast.” A software developer running virtual machines may need memory capacity and multi-core CPU performance. A photographer may benefit from fast storage, sufficient RAM, and supported GPU acceleration. An office-focused user may value battery life, a responsive drive, and reliable connectivity.
Check whether essential software supports the hardware features you are considering. Also consider repairability, ports, display quality, keyboard comfort, and sustained cooling; these can shape daily productivity more than a small benchmark difference.
When possible, look for testing that resembles your intended work rather than relying on a single overall score.
🔄 Optimization Is an Ongoing Trade-Off
Improving one metric can worsen another. Compression may reduce network transfer but use more CPU. Caching can reduce repeated computation but consume memory and risk stale data. Stronger encryption improves protection but adds computational work.
There is rarely one universally fastest design. Engineers choose trade-offs based on response-time goals, cost, reliability, security, energy use, and the expected pattern of demand.
That is why performance work benefits from clear goals. “Make it faster” is vague; “keep search results responsive while handling expected concurrent users” provides a direction for decisions.
🏁 The Core Principle: Remove the Right Limit
More computing power can absolutely improve performance when the added resource is the current constraint and the workload can use it. It can provide valuable headroom, shorten demanding tasks, and support more simultaneous work.
But a system is not a single engine. It is a chain of computation, memory, storage, communication, coordination, and software decisions. The next limiting link determines what users experience.
The strongest habit is therefore simple: define the workload, measure the behavior, locate the bottleneck, and choose a change that fits the evidence.
More computing power produces better performance only when it relieves the constraint that is actually holding the system back. That principle leads to better upgrades, better software, and fewer disappointing “faster” machines. 💻⚙️📈